Uno Adapter Breaks the LLM Speed Ceiling via Diffusion Decoding
The Institute of Foundation Models has unveiled Uno, a diffusion-style adapter that allows existing Large Language Models (LLMs) to generate multiple tokens per step. Unlike traditional autoregressive decoding, which produces text one word at a time, Uno uses a parallelized approach to significantly increase inference speeds and reduce compute costs. Crucially, Uno is designed to attach to existing model weights without retraining, and it provably maintains the original output distribution, ensuring no loss in logic or accuracy. This breakthrough is particularly impactful for the development of real-time AI agents and the reduction of enterprise operational costs. Early debate focuses on the scalability of this adapter approach for frontier-class models and its potential to democratize high-performance AI. By removing the sequential bottleneck of text generation, Uno represents a major step toward making AI interaction instantaneous and economically viable for a wider range of applications.
Opening Insight
The current paradigm of Large Language Model (LLM) interaction is defined by a rhythmic, almost hypnotic visual: the cursor blinking as text appears one word at a time. This is not a stylistic choice by developers, but a technical limitation of the autoregressive architecture. For an AI to predict the next word, it must first finalize the one before it. This linear dependency is the primary bottleneck of modern computing, creating a speed ceiling that affects everything from real-time translation to complex code generation.
The Institute of Foundation Models has now introduced a mechanism that aims to shatter this ceiling. Called "Uno," this diffusion-style adapter allows existing models to generate multiple tokens per step without sacrificing the logical integrity of the output. By decoupling the generation process from its strict one-token-at-a-time shackles, Uno represents a shift from incremental processing to parallelized intuition. It suggests a future where the "thought" process of an AI is no longer a slow crawl, but a sudden crystallization of information.
What Actually Happened
The Institute of Foundation Models unveiled Uno as a specialized adapter designed to attach to the weights of existing autoregressive language models. Unlike traditional methods that require an entirely new model architecture or extensive retraining to improve speed, Uno functions as a modular layer. It utilizes a diffusion-style approach—a technique popularized by image generators like Midjourney or Stable Diffusion—but applies it to the textual decoding process.
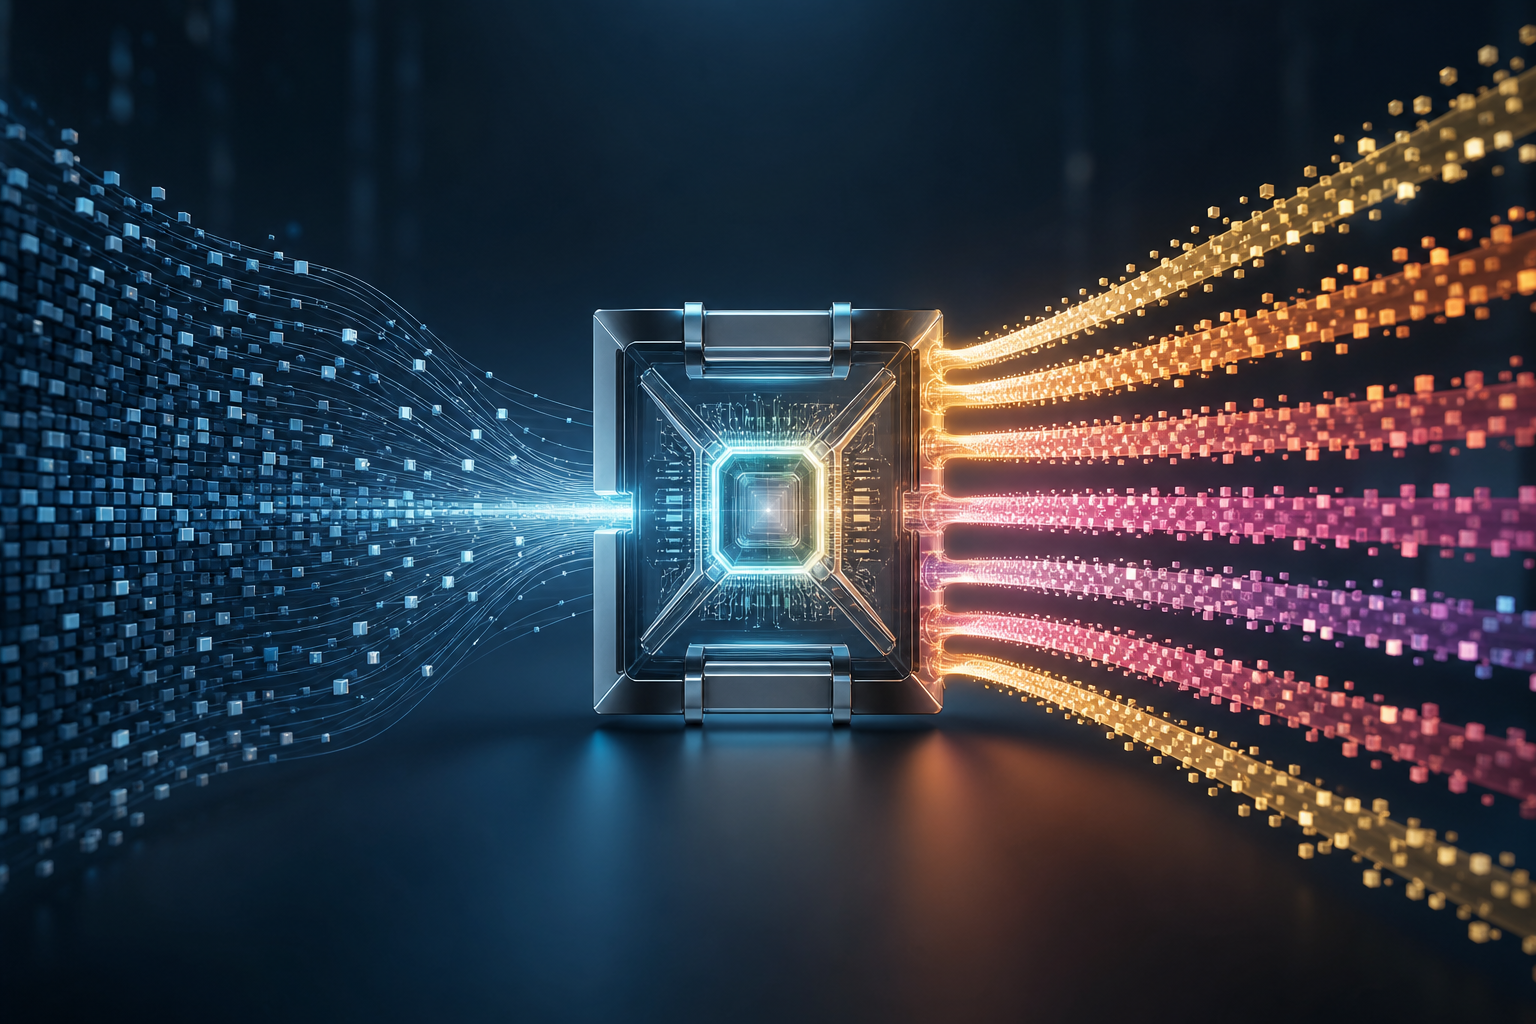
The technical breakthrough lies in Uno's ability to generate multiple tokens simultaneously in a single computational step. In standard LLM decoding, the model calculates the probability of the next token based on all previous tokens. Uno modifies this by predicting a sequence of tokens at once. Crucially, the Institute claims that Uno provably reproduces the same output distribution as standard decoding. This means that while the speed increases, the "personality," logic, and factual accuracy of the base model remain identical to its slower counterpart.
Because Uno is an adapter, it does not necessitate altering the fundamental weights of the base model. Developers can theoretically "plug" Uno into existing high-performing models like GPT-4 or Llama-3, granting them immediate performance boosts. This approach promises significant reductions in inference costs—the price paid by companies to run these models—and a dramatic increase in tokens-per-second for the end-user.
Why It Matters Right Now
Speed in AI is not merely a convenience; it is a prerequisite for autonomy. As we move from chatbots to "agents"—AI systems that perform complex tasks across multiple applications—latency becomes a dealbreaker. An AI agent trying to navigate a web browser or manage a supply chain cannot afford to wait seconds for each sentence of code or reasoning to generate. Uno provides the throughput necessary for these agents to operate in real-time environments.
Furthermore, the economic implications are immediate. The high cost of running LLMs is a primary barrier to widespread enterprise adoption. A significant portion of that cost is tied to GPU compute time. If a model can produce four or five times the amount of text in the same amount of time, the cost per task drops precipitously. This could democratize access to high-tier models that were previously too expensive for small-to-medium businesses to integrate into their workflows.
Finally, the ability to maintain the "same output distribution" is a critical safety and reliability feature. Many speed-up techniques involve "quantization" or "distillation," which often result in a slight degradation of reasoning capability. Uno’s promise to deliver the exact same result faster removes the trade-off between efficiency and intelligence, a hurdle that has plagued AI deployment since the inception of the transformer architecture.
Wider Context
The emergence of Uno sits within a broader geopolitical and technical race to optimize AI efficiency. As reported by Reuters, the realization that "AI is too big and slow" has become a central concern for both technology firms and nation-states. The current reliance on massive, energy-hungry data centers is increasingly viewed as a strategic vulnerability. Technologies that allow models to do more with less—less time, less energy, and fewer chips—are now as valuable as the models themselves.
This development also aligns with a period of intense scrutiny regarding AI safety and guardrails. As the UN and other international bodies debate the governance of these systems, the ability to accurately predict and control model output is paramount. Because Uno preserves the underlying model's distribution, it ensures that existing safety alignments and guardrails remain intact. A faster model that behaves unpredictably is a liability; a faster model that behaves exactly like its validated predecessor is a breakthrough.
The "diffusion-style" mechanism of Uno also hints at a convergence in AI methodologies. Diffusion models have traditionally been the domain of creative media, while autoregressive models ruled the world of logic and language. By borrowing the parallel-processing strengths of diffusion, the Institute of Foundation Models is bridging a gap that could lead to more multimodal systems where text, image, and video are generated with a unified, high-speed logic.
Expert-Level Commentary
The most sophisticated aspect of Uno is its mathematical rigor. The claim that it "provably reproduces" the output distribution suggests a level of verification that is often missing from "black box" AI updates. In technical terms, Uno is likely leveraging the underlying probability space of the base model and using the diffusion adapter to "denoise" a sequence of tokens simultaneously, rather than sampling them one by one.
This is a departure from "speculative decoding," another popular speed-up technique. Speculative decoding uses a smaller, faster "draft" model to guess upcoming tokens, which the larger model then verifies. While effective, it relies on the draft model's accuracy. Uno, by contrast, appears to be an internal optimization of the primary model's own decoding pathway. This reduces the overhead of running two models and potentially offers a more stable path to acceleration.
However, the industry will be watching closely to see how Uno scales with model size. While small adapters work well for medium-sized models (e.g., 7B to 70B parameters), the complexity of the token distribution in frontier models (1T+ parameters) presents a much larger search space for a diffusion adapter to navigate. The efficiency gains may vary based on the specific architecture of the base model it is attached to.
Forward Look
In the short term, we should expect a surge in "Uno-enhanced" open-source models. Developers will likely experiment with attaching these adapters to the Llama and Mistral families of models, creating high-speed versions of popular tools. If the performance gains are as significant as the early reports suggest, this could become the new standard for model deployment, effectively doubling or tripling the "speed limit" of the internet's AI infrastructure.
Looking further ahead, this technology could change how we interact with AI on local devices. Smartphones and laptops have limited thermal and processing budgets. If Uno reduces the compute cycles required for text generation, it makes "on-device" AI—which does not require an internet connection or a remote server—much more viable for complex tasks. This would be a massive win for privacy and latency.
We may also see a shift in how AI training is approached. If inference can be made this efficient through adapters, researchers might focus less on building "small" models and more on building massive, highly capable models that are then "compressed" in time via adapters like Uno. The goal becomes less about making the model small and more about making the model fast.
Closing Insight
The history of computing is a history of removing bottlenecks. We moved from serial ports to parallel processing, and from spinning disks to solid-state drives. The autoregressive nature of LLMs has been the definitive bottleneck of the 2020s—a slow, sequential process in a world that demands instantaneity.
Uno represents more than just a software patch; it is a conceptual shift in how we extract intelligence from neural networks. By proving that we can have the speed of parallel generation without losing the precision of sequential logic, the Institute of Foundation Models has provided a glimpse into a second phase of the AI revolution. In this phase, the barrier between human thought and machine response doesn't just thin—it begins to disappear. The era of the blinking cursor may be coming to a close, replaced by an AI that doesn't just speak, but thinks in entire paragraphs. Qualifying this progress, however, will remain the task of those who must now keep pace with a machine that no longer waits for them.